Torus Foundry

Unlock grid capacity

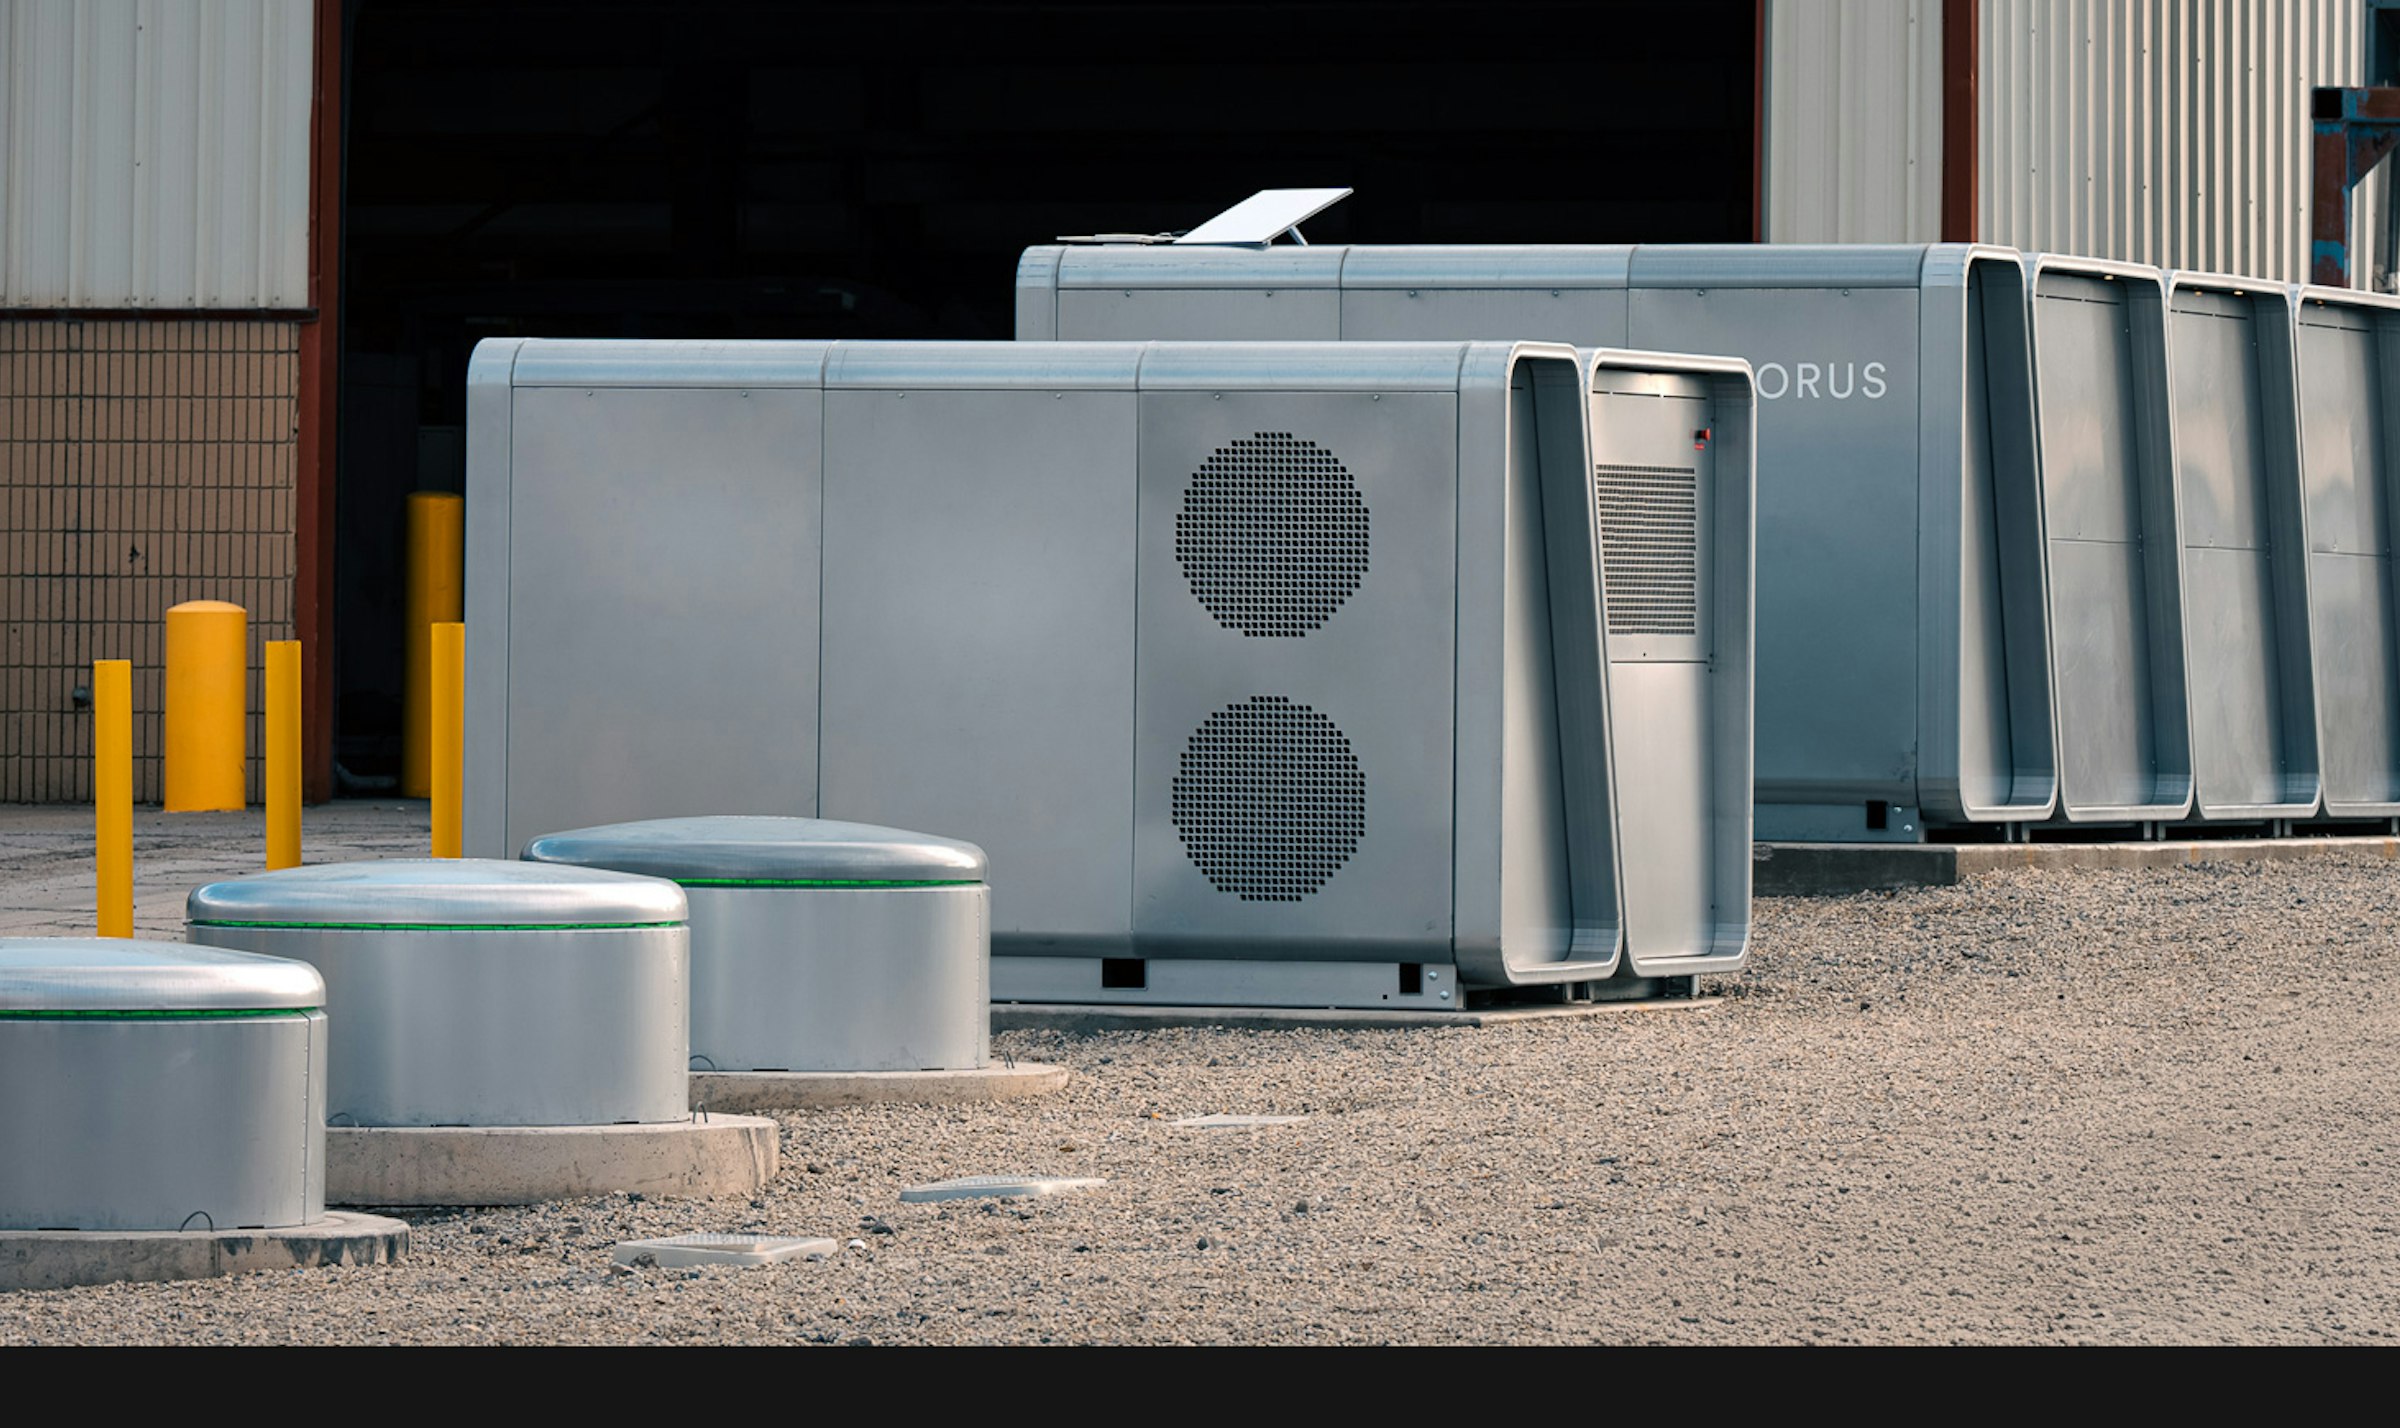
Torus Foundry pairs modular AI infrastructure with built-in energy storage and management that unlocks grid capacity that would otherwise sit idle, speeding up time to token.

Deploy based on demand, not construction or utility timelines.

Available power is the biggest constraint to deploying AI compute. Hybrid energy storage peak shaves and load shifts at every Foundry site, easing congestion and unlocking additional capacity to power more GPUs.

1

Unlock unused grid capacity to power AI workloads

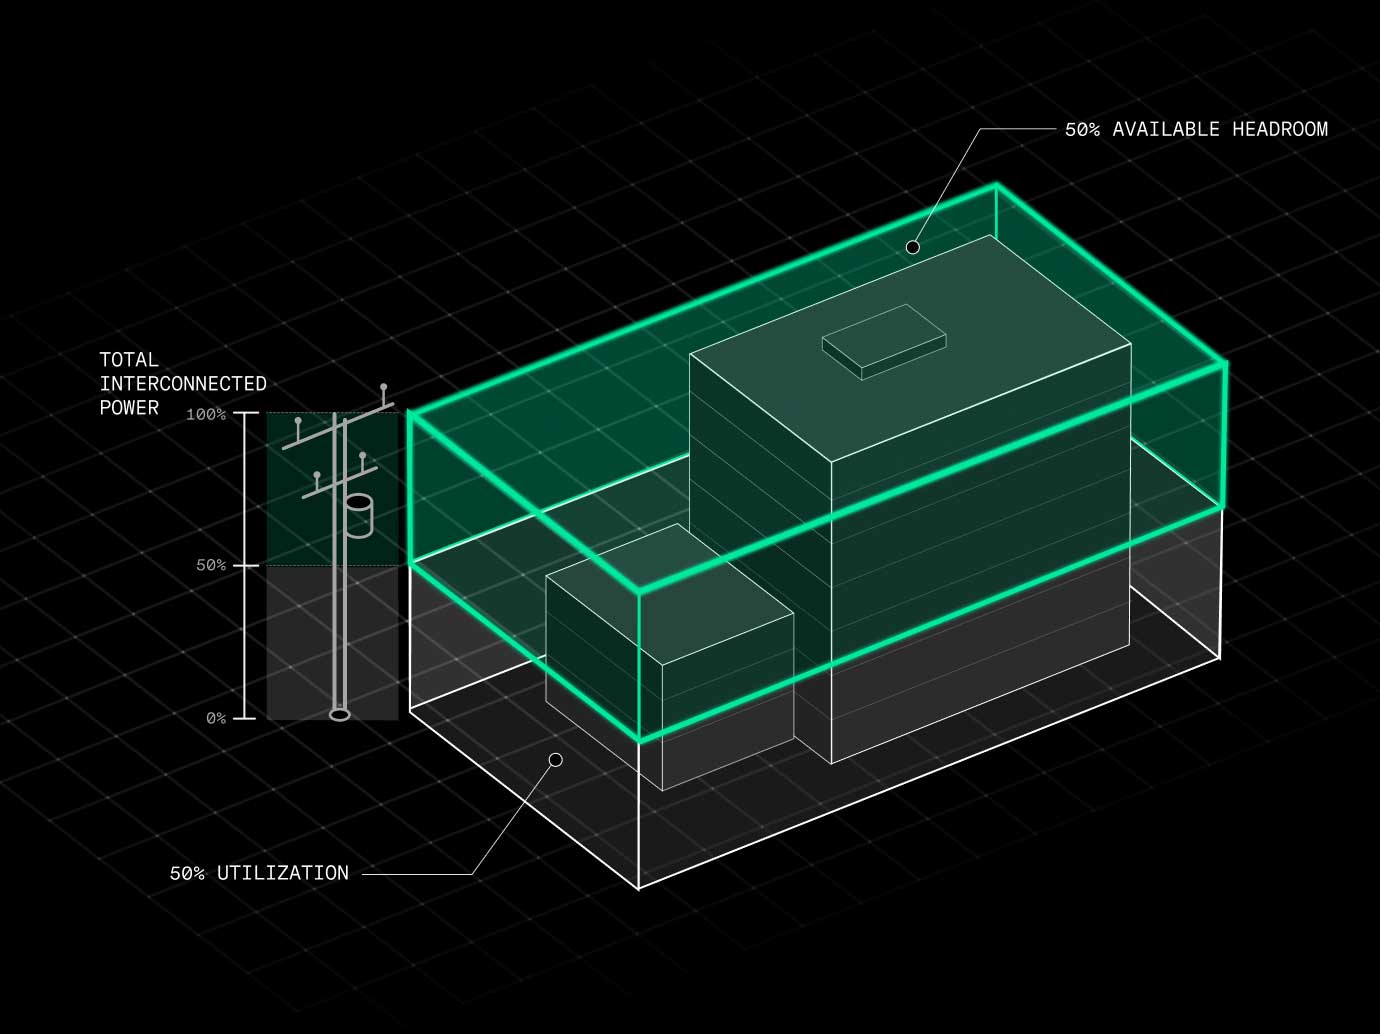
Commercial and industrial sites are sized for peak demand but only hit it a fraction of the time. Foundry installs behind the meter at developed sites and pairs with Reserve to tap into that unused headroom. 

2

More GPUs from the same grid connection

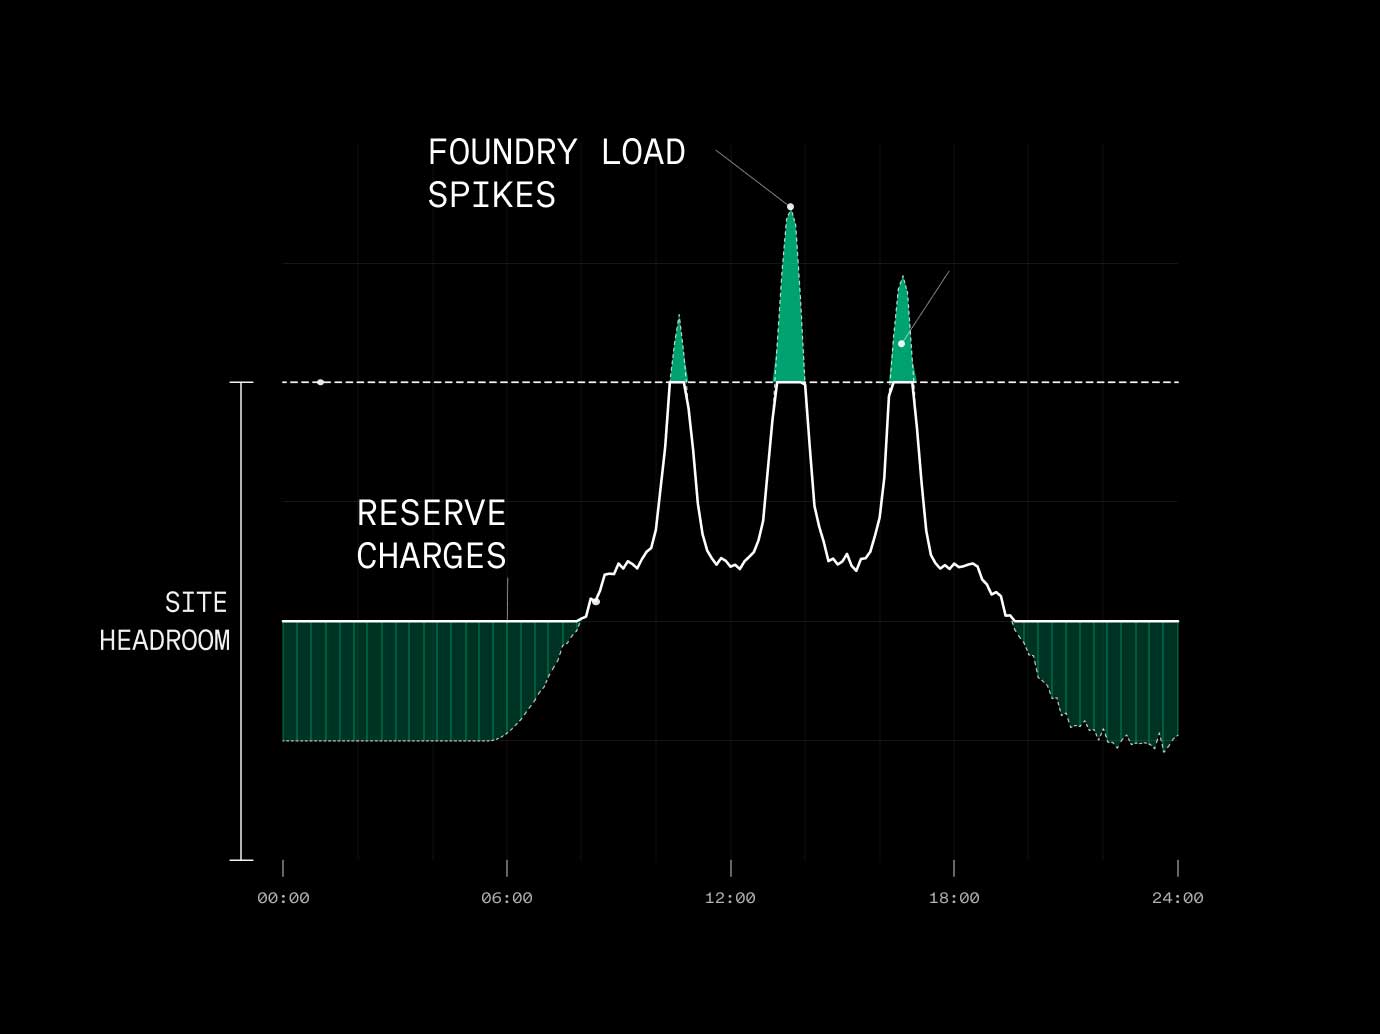
Reserve charges from the grid when site demand is low and discharges to cover compute load spikes that exceed the site's interconnection limit. That means Foundry can operate above the site's capacity to power more IT load.
3

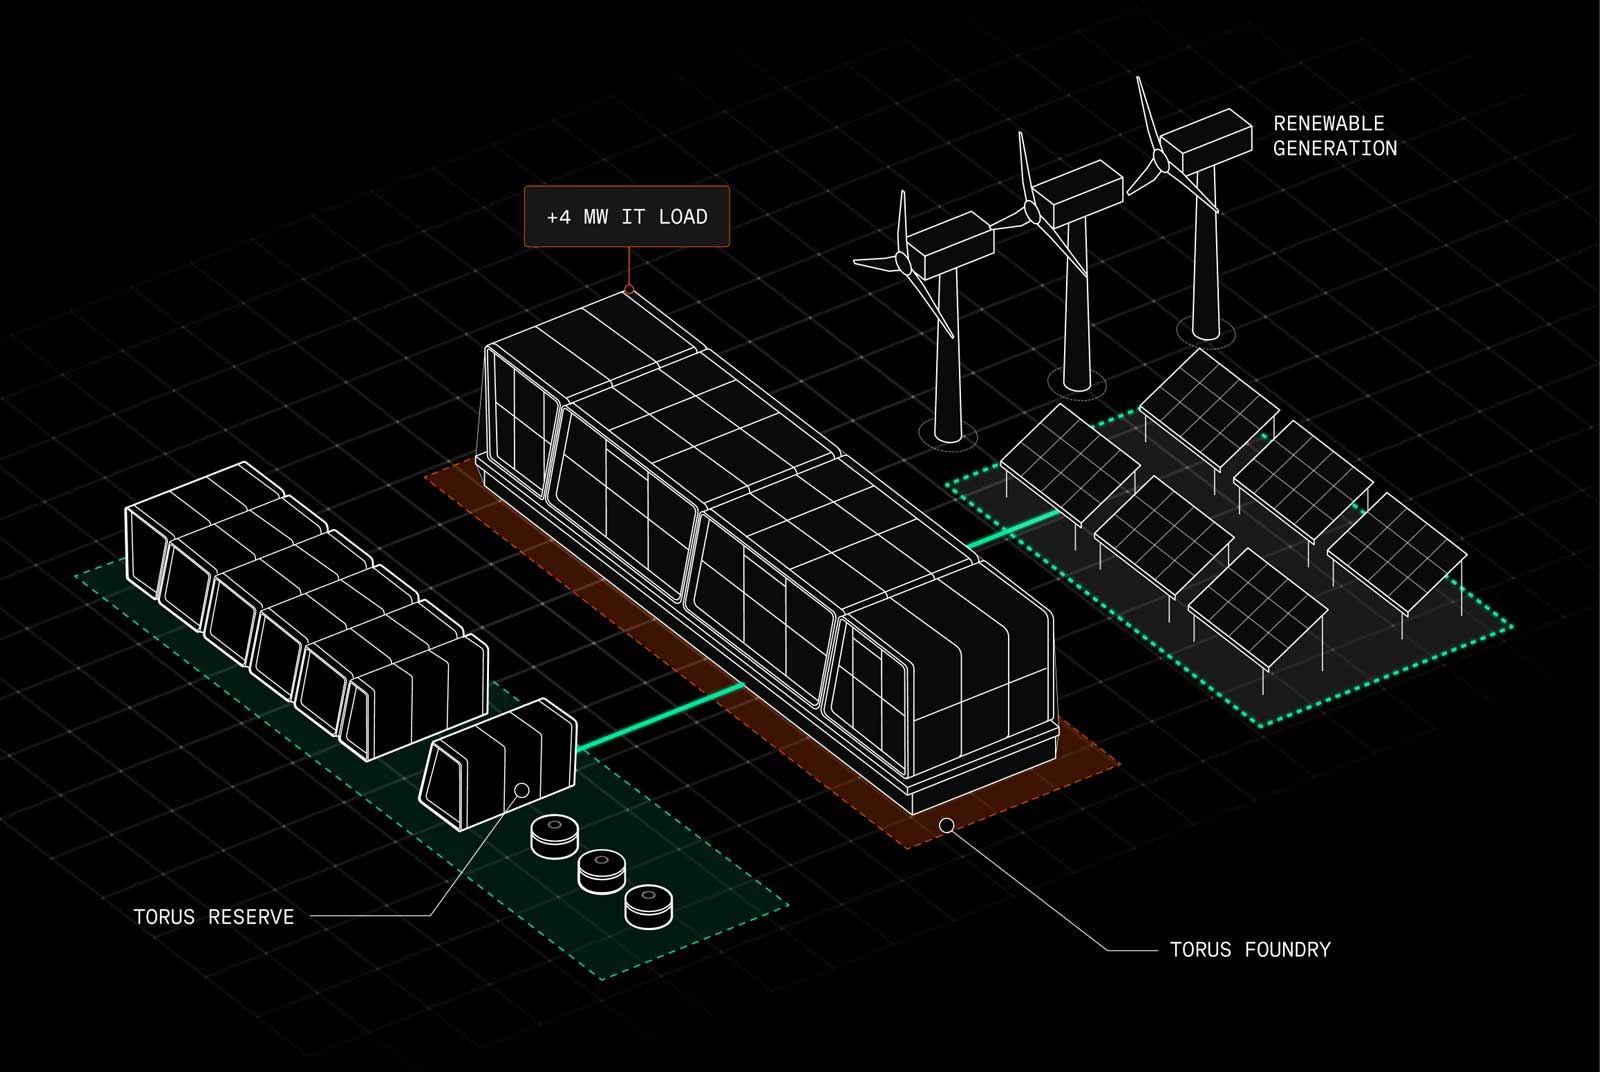
Scale quickly by pairing onsite generation

Reserve coordinates multiple sources of generation to meet load and turns on-site renewables into firm, reliable power. Every source added increases the number of powered GPUs on site. 
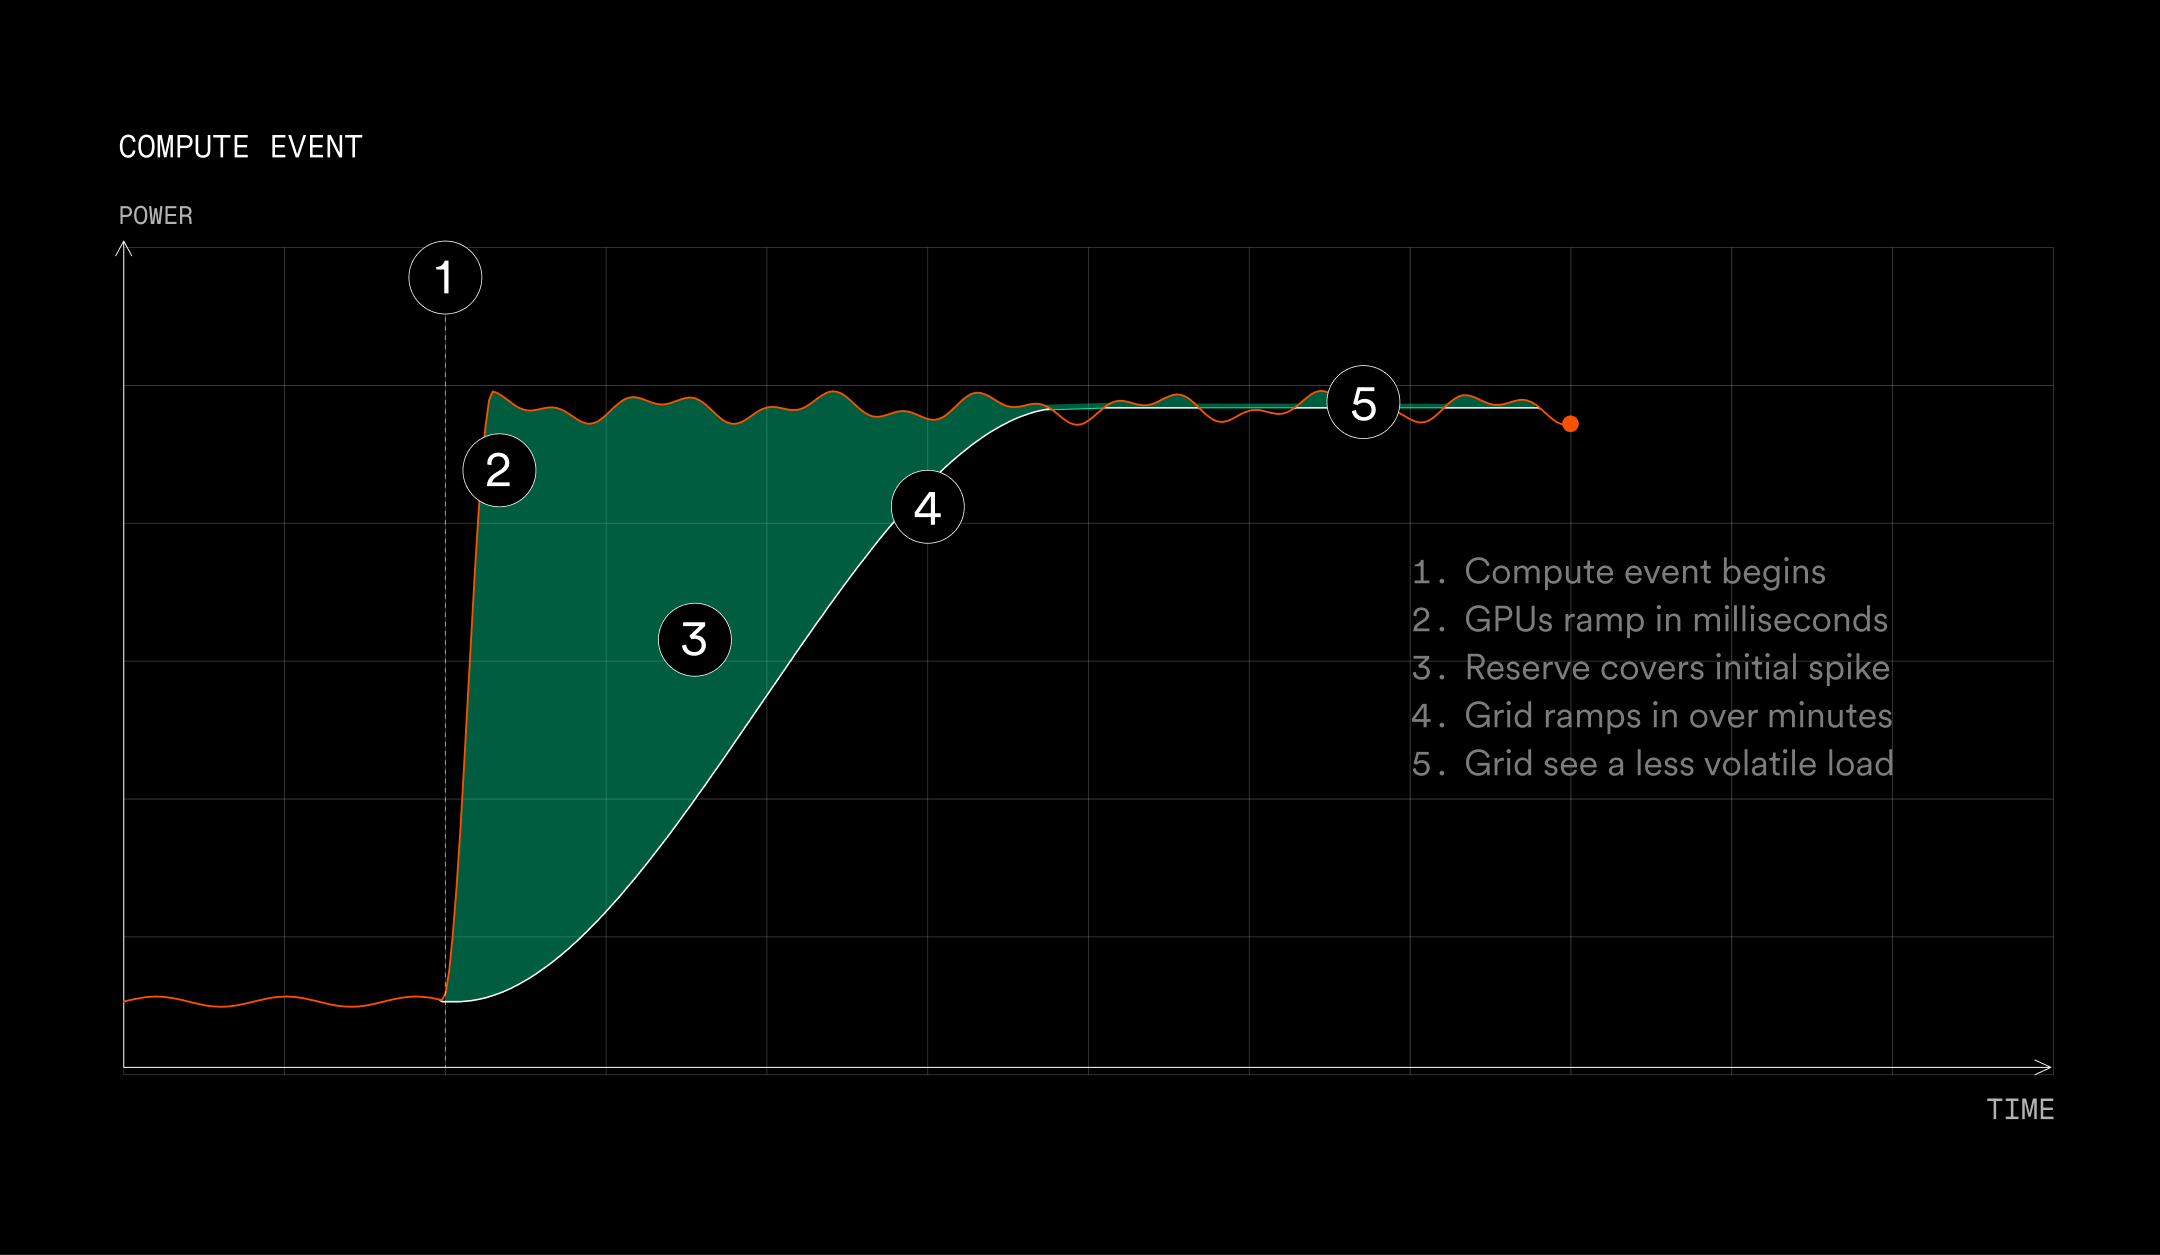
Real time load shaping

Reserve automatically responds to Foundry’s load as it changes and discharges to keep the grid-side draw under the service limit. The GPUs run at full output, and the utility sees a smooth, predictable load.

How Foundry speeds up time to token

Your questions, answered.

Secure inference capacity, ready today.
Share your target capacity and go-live date. We’ll build a plan to meet that roadmap.