Torus Foundry

Deploy sovereign inference compute

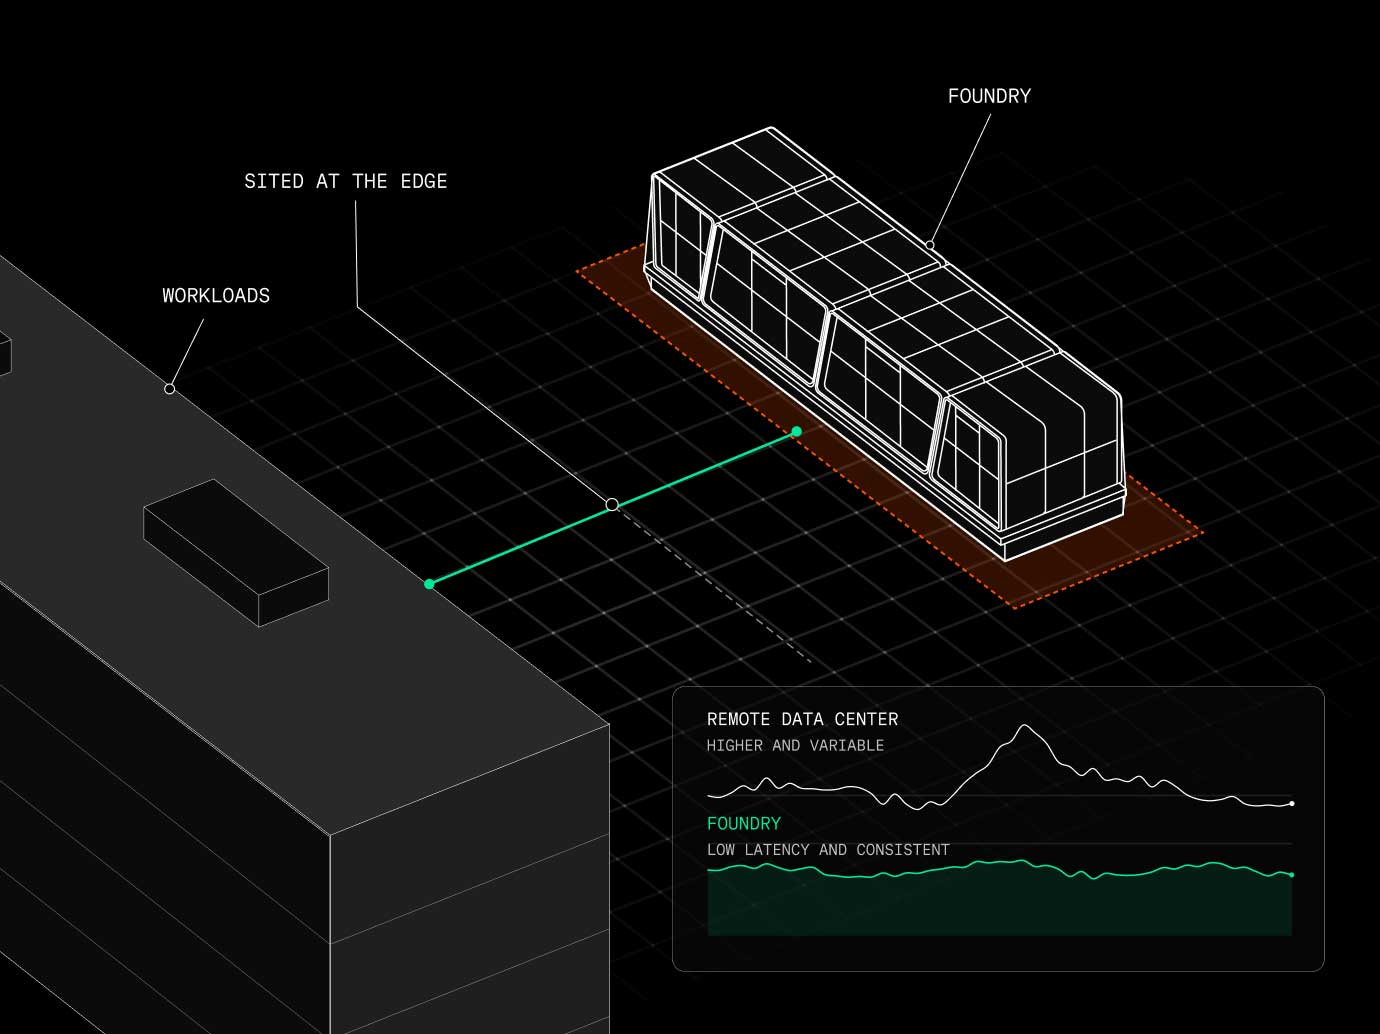
Foundry deploys single-tenant compute units, close to the workloads they serve.

AI infrastructure sited next to the load it serves

Inference compute next to your workloads, dedicated to them. Torus delivers it fully containerized and provides lifetime system maintenance.

How it works

1

Compute sits next to your workloads

Foundry units are sited near where your workloads run, so requests take a short route instead of crossing a region to a remote data center. Response times drop and stay consistent, even at peak.

2

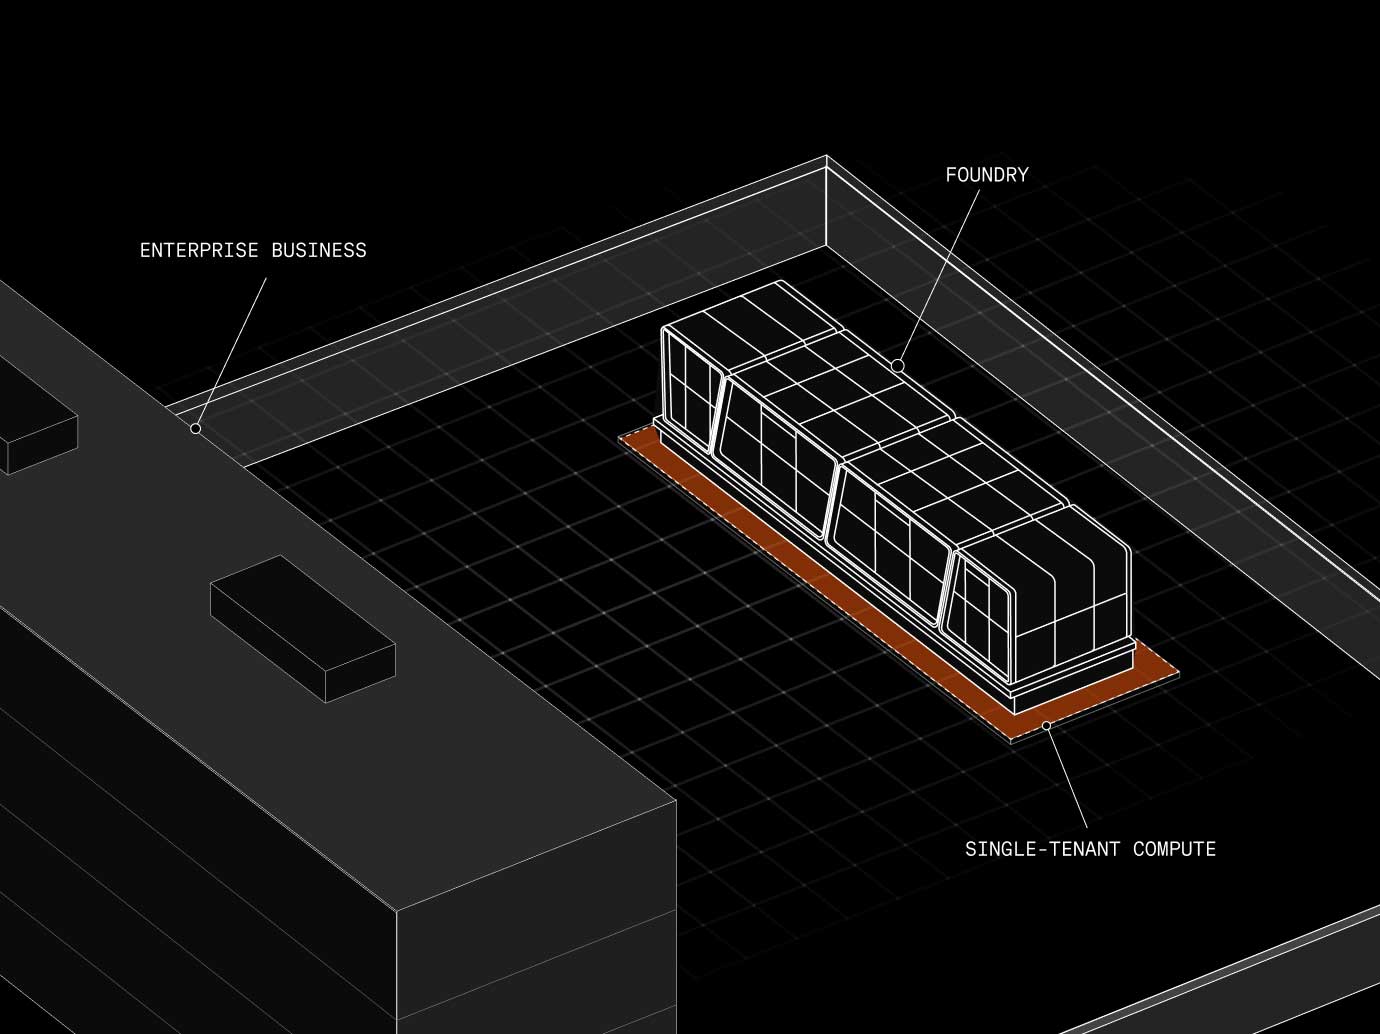
Single-tenant by design

Each Foundry unit can serve one customer. Your models and data run on dedicated hardware sited close to your workloads, with no other tenants’ systems sharing the space.
3

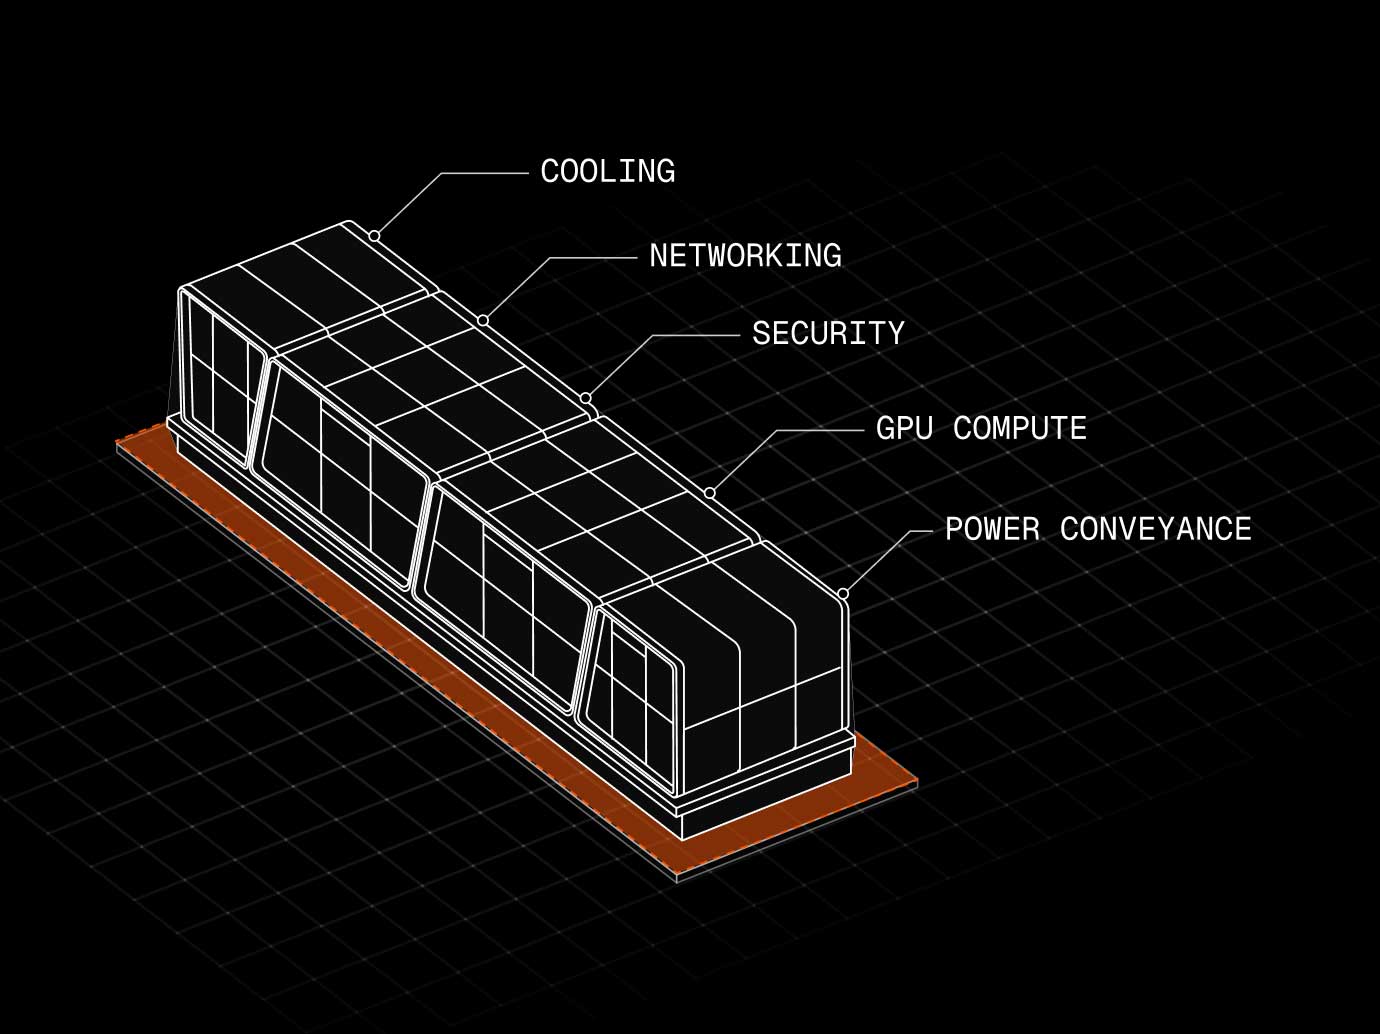
Fully containerized AI infrastructure

Torus delivers a fully containerized unit through a single vendor, so your team doesn’t have to piece together racks, cooling, power distribution, networking, and fiber. We also provide lifetime system maintenance, giving you one partner from installation through ongoing operation.

Built-in physical and cybersercurity

Torus Protect, the security layer built into every Torus Foundry, guards the unit on both the network side and the physical side. A Zero Trust firewall verifies every connection, data is encrypted in transit and at rest, and no other customer’s systems share your unit.
How Foundry speeds up time to token

Your questions, answered.

Secure inference capacity, ready today.
Share your target capacity and go-live date. We’ll build a plan to meet that roadmap.